It's impossible to guarantee a long timeframe because of entropy (also called death!). Digital data decay and dies, just like any other thing in the universe. But it can be slowed down.
There's currently no fail-proof and scientifically proven way to guarantee 30+ years of cold data archival. Some projects are aiming to do that, like the Rosetta Disks project of the Long Now museum, although they are still very costly and with a low data density (about 50 MB).
In the meantime, you can use scientifically proven resilient optical mediums for cold storage like Blu-ray Discs HTL type like Panasonic's, or archival grade DVD+R like Verbatim Gold Archival, and keep them in air-tight boxes in a soft spot (avoid high temperature) and out of the light.
Also be REDUNDANT: Make multiple copies of your data (at least 4), and compute hashes to check regularly that everything is alright, and every few years you should rewrite your data on new disks. Also, use a lot of error correcting codes, they will allow you to repair your corrupted data!
Long answer
Why are data corrupted with time? The answer lies in one word: entropy. This is one of the primary and unavoidable force of the universe, which makes systems become less and less ordered in time. Data corruption is exactly that: a disorder in bits order. So in other words, the Universe hates your data. //
Long-Term Archival
Even with the best currently available technologies, digital data can only be cold stored for a few decades (about 20 years). Thus, in the long run, you cannot just rely on cold storage: you need to setup a methodology for your data archiving process to ensure that your data can be retrieved in the future (even with technological changes), and that you minimize the risks of losing your data. In other words, you need to become the digital curator of your data, repairing corruptions when they happen and recreate new copies when needed.
There's no foolproof rules, but here are a few established curating strategies, and in particular a magical tool that will make your job easier:


Purge Old SpiderOak files
SpiderOak keeps an unlimited number of previous versions. This doesn't cause a problem in most cases, but can be an issue for files that change frequently, particularly if you backup multiple times a day or if the files don't compress very well. So I've created a batch file to handle this for you. You do not need to run it often, but maybe once or twice a year it can save you a lot of space.
The file takes a while to run, more time when more needs to be deleted, so be patient. It will keep the daily backups copies for 10 days, weekly for 10 weeks, monthly for 12 months and one a year thereafter. This should be more than enough for most purposes. Clicking on the batch file will close SpiderOak, open a command console, delete the historical file, update the history records, restart SpiderOak and close the command console. I have it reporting everything it does, so you can watch if you like.
The text file I've also posted will explain the 6 lines of the batch file in case you want to adjust the parameters I've chosen, or see how it works.
Just copy the config.xml, cert.pem and key.pem. I actually have a Syncthing folder setup on remote devices to sync that back to a trusted local machine (folders are setup send-only, receive-only).
If you save the config.xml the remote Device IDs and folder IDs (as well as local paths) are already saved.
If you save the cert.pem and key.pem you have saved your own device ID. It is impossible to recreate the Device ID without these, so saving the local device fingerprint (“Device ID”) is unnecessary.
No need to make note of all those folder IDs and remote device IDs unless you want to reconstruct the config because the config.xml was not saved.
As long as the local folder paths are the same:
- For safety, set all the remote folders to “Send Only”.
- Install Syncthing on the replacement device (wait for an automatic upgrade if needed).
- Stop Syncthing.
- Copy over the config.xml, cert.pem and key.pem that you saved from the old device.
- Start Syncthing.
- It will see that the folders don’t exist and should create them and copy files back.
- Once they are in sync, set the remote folders back to “Send & Receive”.
Note that any .stignore files you had on the old device will be lost because they are not synced, and do not get stored in the config.xml.
One workaround is to use an #include file in the .stignore and maintain the Ignore patterns there. But it makes maintenance more onerous because to edit the ignore patterns you have to open that file with another app.
Where its possible, you can use identical ignore patterns on both sides; it is redundant, but it preserves the patterns. This is not always possible.
A final alternative is to run a periodic script to copy every .stignore to device-parent-folder.stignore (where device- is hard-coded in your script). This file would be synced.
Many applications create and manage directories containing cached information about content stored elsewhere, such as cached Web content or thumbnail-size versions of images or movies. For speed and storage efficiency we would often like to avoid backing up, archiving, or otherwise unnecessarily copying such directories around, but it is a pain to identify and individually exclude each such directory during data transfer operations. I propose an extremely simple convention by which applications can reliably "tag" any cache directories they create, for easy identification by backup systems and other data management utilities. Data management utilities can then heed or ignore these tags as the user sees fit.
A pool is a collection of vdevs. Vdevs can be any of the following (and more, but we’re keeping this relatively simple):
single disks (think RAID0)
redundant vdevs (aka mirrors – think RAID1)
parity vdevs (aka stripes – think RAID5/RAID6/RAID7, aka single, dual, and triple parity stripes)
The pool itself will distribute writes among the vdevs inside it on a relatively even basis. //
striped (RAIDZ) vdevs aren’t supposed to be “as big as you can possibly make them.” Experts are cagey about actually giving concrete recommendations about stripe width (the number of devices in a striped vdev), but they invariably recommend making them “not too wide.” If you consider yourself an expert, make your own expert decision about this. If you don’t consider yourself an expert, and you want more concrete general rule-of-thumb advice: no more than eight disks per vdev. //
According to Dell, “Raid 5 for all business critical data on any drive type [is] no longer best practice.”
RAIDZ2 and RAIDZ3 try to address this nightmare scenario by expanding to dual and triple parity, respectively. This means that a RAIDZ2 vdev can survive two drive failures, and a RAIDZ3 vdev can survive three. Problem solved, right? Well, problem mitigated – but the degraded performance and resilver time is even worse than a RAIDZ1, because the parity calculations are considerably gnarlier. And it gets worse the wider your stripe (number of disks in the vdev). //
When a disk fails in a mirror vdev, your pool is minimally impacted – nothing needs to be rebuilt from parity, you just have one less device to distribute reads from. When you replace and resilver a disk in a mirror vdev, your pool is again minimally impacted – you’re doing simple reads from the remaining member of the vdev, and simple writes to the new member of the vdev. In no case are you re-writing entire stripes, all other vdevs in the pool are completely unaffected, etc. Mirror vdev resilvering goes really quickly, with very little impact on the performance of the pool. Resilience to multiple failure is very strong, though requires some calculation – your chance of surviving a disk failure is 1-(f/(n-f)), where f is the number of disks already failed, and n is the number of disks in the full pool. In an eight disk pool, this means 100% survival of the first disk failure, 85.7% survival of a second disk failure, 66.7% survival of a third disk failure. This assumes two disk vdevs, of course – three disk mirrors are even more resilient.
But wait, why would I want to trade guaranteed two disk failure in RAIDZ2 with only 85.7% survival of two disk failure in a pool of mirrors? Because of the drastically shorter time to resilver, and drastically lower load placed on the pool while doing so. The only disk more heavily loaded than usual during a mirror vdev resilvering is the other disk in the vdev – which might sound bad, but remember that it’s no more heavily loaded than it would’ve been as a RAIDZ member. //
Too many words, mister sysadmin. What’s all this boil down to?
- don’t be greedy. 50% storage efficiency is plenty.
for a given number of disks, a pool of mirrors will significantly outperform a RAIDZ stripe. - a degraded pool of mirrors will severely outperform a degraded RAIDZ stripe.
- a degraded pool of mirrors will rebuild tremendously faster than a degraded RAIDZ stripe.
- a pool of mirrors is easier to manage, maintain, live with, and upgrade than a RAIDZ stripe.
- BACK. UP. YOUR POOL. REGULARLY. TAKE THIS SERIOUSLY.
Not everything belongs in one place
Maybe decentralization isn’t bad after all?
Air-gapped backups are underrated
Never underestimate those portable drives
Sync is not backup. Backup is not an archive
I wish I had understood this earlier
My current hybrid model has a cloud for its convenience, making things easier to share with anyone, not on my local network. NAS is in the middle, taking up the primary storage duties of keeping my files in sync across devices, ensuring everything important is backed up, and helping me access my files swiftly. And finally, my collection of hard drives lets me keep my archives safe. //
https://www.xda-developers.com/why-i-went-hybrid-with-nas/?post=628a-45d3-94a48a0b6521#thread-posts
Tom
Well, to each their own.
Personally, I start with my personal PC: OS is on a 2 TB NVMe, with separate NVMe drives for games and software, plus an 8 TB HDD. Nextcloud syncs fully to that HDD. My full profile (Desktop, Downloads, Documents, etc.) is mirrored to a Nextcloud folder using MirrorFolder.
So:
Copy 1 = C drive
Copy 2 = 8 TB HDD
Copy 3–4 = Server-side DrivePool (two 20 TB HDDs, full duplication)
Copy 5 = Carbonite backup of DrivePool
My C drive is image-backed daily (incremental, with full every 5 days, keeping the last 10). Those go to a 4 TB external, then Kopia on the server backs them up again. Only the full (5th-day) images are sent to Carbonite.
Photo backups reach PhotoPrism either via the photo folder on C that's bi-directionally mirrored to the photo prism folder (scanned with a python script using the API), or from Android via PhotoSync/Syncthing. These folders live on the same 20 TB DrivePool (duplicated and backed up). Audiobookshelf, Komga, etc., also live there.
Plex Media sits on two separate DrivePools (via QNAP TL-D800S DAS units with miniSAS). No duplication—about 100 TB—so Backblaze handles that.
Why both Carbonite and Backblaze? I want Nextcloud and critical items uploaded immediately, not delayed behind TBs of media. I use NetLimiter to cap combined upload to ~75%, letting it auto-balance bandwidth between the two.
That’s it. Fully backed, accessible via reverse proxies. No Google needed—Google Photos? See Immich and PhotoPrism.

rsync -rin --ignore-existing "$LEFT_DIR"/ "$RIGHT_DIR"/|sed -e 's/^[^ ]* /L             /'
rsync -rin --ignore-existing "$RIGHT_DIR"/ "$LEFT_DIR"/|sed -e 's/^[^ ]* /R             /'
rsync -rin --existing "$LEFT_DIR"/ "$RIGHT_DIR"/|sed -e 's/^/X /'
DVDs, if taken care of properly, should last for 30 to up to 100 years. It turned out that the problems that Bumbray had weren't due to a DVD player or poor DVD maintenance. In a statement to JoBlo shared on Tuesday, WBD confirmed widespread complaints about DVDs manufactured between 2006 and 2008. The statement said:
Warner Bros. Home Entertainment is aware of potential issues affecting select DVD titles manufactured between 2006 – 2008, and the company has been actively working with consumers to replace defective discs.
Where possible, the defective discs have been replaced with the same title. However, as some of the affected titles are no longer in print or the rights have expired, consumers have been offered an exchange for a title of like-value. //
Damn Fool Idealistic Crusader noted that owners of WB DVDs can check to see if their discs were manufactured by the maligned plant by looking at the inner ring codes on the DVDs' undersides. //
evanTO Ars Scholae Palatinae
7y
839
DRM makes it difficult, and in some cases impossible, for people to make legitimate backups of their own media. Not being able to legally do this, particularly as examples like this article abound, is just one more example of how US Copyright Law is broken.
If you keep critical data in your pod and require your own daily backup, then our incremental backups to external S3 storage are the best solution. They can be triggered manually or daily at night and take incremental, encrypted, deduplicated and compressed snapshots using Restic. This has the benefit that only changed files are copied and the backup doesn’t need as much space. You can also provide your own S3-based storage, which moves the data to another company for extra redundancy.

Features
Create backups locally and remotely
Set a schedule for regular backups
Save time and disk space because Pika Backup does not need to copy known data again
Encrypt your backups
List created archives and browse through their contents
Recover files or folders via your file browser
Pika Backup is designed to save your personal data and does not support complete system recovery. Pika Backup is powered by the well-tested BorgBackup software.
vaultwarden data should be backed up regularly, preferably via an automated process (e.g., cron job). Ideally, at least one copy should be stored remotely (e.g., cloud storage or a different computer). Avoid relying on filesystem or VM snapshots as a backup method, as these are more complex operations where more things can go wrong, and recovery in such cases can be difficult or impossible for the typical user. Adding an extra layer of encryption on your backups would generally be a good idea (especially if your backup also includes config data like your admin token), but you might choose to skip this step if you're confident that your master password (and those of your other users, if any) is strong.
Backup vaultwarden (formerly known as bitwarden_rs) SQLite3/PostgreSQL/MySQL/MariaDB database by rclone. (Docker)
Jaycuse
I recommend having a read at the wiki
https://github.com/dani-garcia/vaultwarden/wiki/Backing-up-your-vault
I use the docker image bruceforce/bw_backup
My docker compose settings:
bw_backup:
  image: bruceforce/bw_backup
  container_name: bw_backup
  restart: unless-stopped
  init: true
  depends_on:
    - bitwarden
  volumes:
    - bitwarden-data:/data/
    - backup-data:/backup_folder/
    - /etc/timezone:/etc/timezone:ro
    - /etc/localtime:/etc/localtime:ro
  environment:
    - DB_FILE=/data/db.sqlite3
    - BACKUP_FILE=/backup_folder/bw_backup.sqlite3
      # EVERY DAY 5am
    - CRON_TIME=0 5 * * *
    - TIMESTAMP=false
    - UID=0
    - GID=0
Once I have the backup file I use borg backup al
Backing up data
By default, vaultwarden stores all of its data under a directory called data (in the same directory as the vaultwarden executable). This location can be changed by setting the DATA_FOLDER environment variable. If you run vaultwarden with SQLite (this is the most common setup), then the SQL database is just a file in the data folder. If you run with MySQL or PostgreSQL, you will have to dump that data separately --
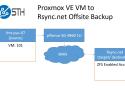
Today we have a quick guide on how to automate Proxmox VE ZFS offsite backups to Rsync.net. The folks at rsync.net set us up with one of their ZFS enabled trial accounts. As the name might imply, Rsync.net started as a backup service for those using rsync. Since then they have expanded to allowing ZFS access for ZFS send/ receive which makes ZFS backups very easy. In our previous article we showed server-to-server backup using pve-zsync to automate the process.
• Backup test
This is very primitive and is unix-centric, but if I rsync from a source to a destination, I will do the following on both:
 # find /backup | wc -l
 # du -ah /backup | tail -1
... and I expect them to be identical (or nearly so) on both ends. Again, very blunt tooling here and this is after a successful, no errors rsync ... but I'm feeling good at that point.

QUICK ANSWER
Backup Android devices using Google One by going to Settings > Google > All services > Backup and toggling on Backup by Google One. You can tap on Back up now if you don't want to wait for your phone to update automatically.
JUMP TO KEY SECTIONS
- How to backup your Android phone with Google
- How to backup your Android phone with Amazon Photos, OneDrive, and others
- Backing up to your computer
- Other options

For C-suite execs and security leaders, discovering your organization has been breached by network intruders, your critical systems locked up, and your data stolen, and then receiving a ransom demand, is probably the worst day of your professional life.
But it can get even worse, as some execs who had been infected with Hazard ransomware recently found out. After paying the ransom in exchange for a decryptor to restore the encrypted files, the decryptor did not work. //
Headley_GrangeSilver badge
"For C-suite execs and security leaders, discovering your organization has been breached, your critical systems locked up and your data stolen, then receiving a ransom demand, is probably the worst day of your professional life."
Third worst, surely.
Second worst is finding out that your bonus is reduced because of it.
First worst is discovering that someone can prove that it's your fault. //
lglethalSilver badge
Go
Paying the Dane Geld
Pay the Geld, and you'll never get rid of the Dane...
What was true so many years ago, remains true to today... //
Doctor SyntaxSilver badge
These guys are just getting ransomware a bad name. //
ThatOneSilver badge
Facepalm
Hope springs eternal
pay the extortionists – for concerns about [obvious stuff]
...Except that you're placing all your hopes on the honesty of criminals!...
Once you've paid them, why would they bother decrypting your stuff? Why wouldn't they ask for even more money, later (or immediately)? Why wouldn't they refrain from gaining some free street cred by reselling all the data they have stolen from you?
Your only hope is that they are honest, trustworthy criminals, who will strive to make sure to repair any damage they've caused, and for whom your well-being is the most important thing in the world...
I think you would be better advised to avoid clicking on that mysterious-yet-oh-so-intriguing link, but that's me. //
3 days
ChrisCSilver badge
Reply Icon
Re: Hope springs eternal
Doesn't matter whether they use the same name or a different one for each victim, the point is that if word gets around that a ransomware group is ripping off people who've paid up, then people are going to be increasingly unlikely to trust any ransomware group.
And at that point, there's a fairly good chance that at least one of the "trustworthy" groups may well decide to take whatever action is needed to deal with this threat to their business model - given the nature of such groups and the dark underbelly of society in which they operate, it's not unreasonable to consider that such action may well be rather permanent to the recipients...
Basic
Free
10 GB
No credit card required
IDrive® Mini
$2.95 per year One user
100 GB
$9.95 per year
500 GB
IDrive® Personal
$99.50/year$69.65 first year
One user, Multiple computers
5 TB Storage