eldakka
Reply Icon
Re: Justice for bcachefs!
Not properly, it doesn't re-stripe the existing data like mdadm or btrfs, it just evens out the disk usage.
A 3 disk raid5 expanded to 5 will inherit the same 50% parity overhead for existing data,
And that can be solved by a simple mv and copy back the file. e.g.
mv $i $i.tmp && cp -p $i.tmp $i && rm $i.tmp
Stick that (or your own preference, using rsync for example) in a simple script/find command to recurse it (with appropriate checks/tests etc.), and that'll make the 'old' data stripe 'properly' across the full RAID width.
eldakka
Reply Icon
Re: Justice for bcachefs!
is as much a "simple solution" and so divorced from the behaviour we'd get if ZFS did the re-striping itself* that you may as well say we don't need ZFS to do snapshots for us, we could write our own simple script to, ooh, create a new overlay/passthrough file system, change all the mount points, halt all processes with writable file handles open... (yes, yes, I'm being hyperbolic).
I never said it shouldn't be something ZFS does transparently. I never said it would be a bad idea or unnecessary thing for ZFS to support.
I was merely pointing out that it is a fairly simple thing to work around such that maybe the unpaid ZFS devs feel they have more important things to work on for now. I mean, it's taken the best part of 20 years to even get the ability to expand a RAIDZ vdev at all.
I'll also say that if anyone actually cares about the filesystem they are using, making conscious decisions to choose a filesystem like ZFS or whatever, then they are not a typical average user. Typical average users don't create ZFS arrays of multiple disks in various raidz/mirror volumes and then grow them. That is not the use-case of an average user.
Later (below) you say "production-ready", why are you messing around with growing raidz vdevs and wanting to re-stripe them to distribute across the array? That is a hobbyist/homelab-type situation. If you are using ZFS in a production environment - that is revenue/income is tied to it - then the answer is to create a new raidz and migrate (zfs-send/receive) data to it. No messing about with growing raidz vdevs and re-striping the data, that's just totally unnecessary.
e.g. 'beneath' the user file access level with no possibility of access control issues,
If you run the mv and cp as root, then there will be no access control issues, cp -p (as root) will preserve file permissions and FACLs.
not risking problems when changing your simplistic commands into production-ready "appropriate check/tests etc" like status reports, running automatically, maybe even backing off when there is a momentary load increase so the whole server isn't bogged down as the recursive cp
If you system gets bogged down from doing a single file copy, then I think you have a system problem.
chews the terabytes,
Why would it chew terabytes? Unless you have TB-sized files, it won't. Recursive doesn't mean what I think you think it means. It does not mean "in parallel". The example I gave will work on a single file at a time in a serial process, and will not move onto the next file until the current file is complete (tehniically it won't move on at all, it's the inner part of a loop you'd need to feed a file list to it). Therefore no extra space beyond the size of the currently being worked on file is needed.
not risking losing track when your telnet into the server shell dies
Why would that do anything? At worst you'll have a single $i.tmp file that you might have to manually do the cp back to the original ($i) name. There will be no data loss (and especially not if you snapshot it first). And even if you 'lose track', just start again, no biggie, will just take longer as you're redoing some of the already done work.
And as I said, you can use things like rsync instead, which would give you the ability to 'keep track' instead. The command I pasted was just the simplest one to give an idea of what is needed, just making a new copy of the file will re-stripe it across the full raidz. Or if you have your pool split up into many smaller filesystems rather than just a single one for the entire pool, then you can zfs-send/receive the filesystem to a enw filesystem in the same pool then use "zfs set mountpoint=<oldmountpoint>) to give the new filesystem the same mountpoint as the old one, then delete the old one.
(not risking a brainfart and doing all that copying over the LAN and back again!) - and simply being accessible to Joe Bloggs ZFS user who just would like it all to work, please.
I agree, it would be. But it doesn't. I'm pointing out that there is a solution to the issue the poster I am replying to mentioned. It is annoying to have to do (I've done it when I changed the recordsize of my filesystems), but it can be done, and it's not particularly difficult.
If someone is going to choose something like ZFS, I'd expect them to be able to do internet searches on topics like this and get help from technical forums or various guides that people have written to cover this sort of use-case. There are guides and instructions on how to do this sort of thing.
Anonymous Coward
Re: Oh I don't want to feel bad
That's because the article is glossing overstreet's persistent refusal to follow basic patch submission procedures, along with his high-handed approach to any criticism of his behaviour or submissions.
The article tries to frame it as a clash of personalities, as if it's an entirely subjective emotional issue on the part of the kernel developers, but the reality is that overstreet is (perhaps deliberately) refusing to conform to the technical requirements for participation. //
wpeckham
Missing the point
Developers made two points here and most comments ignore both.
#1 Development in a company is driven by projects and dollars. Development in the Kernel is driven by community! A toxic member of the community cannot be, and should not be, trusted.
#2 To a developer features are a nice ting to pursue, but the gold standard involves correctness, elegance, and MAINTAINABILITY! You might like that greater feature set, but if it does not integrate with existing code safely or does not present in a way that the other developers can maintain then it is a trap. Using bad or misleading code is to set landmines on your yard. Don't.
Choices must be made, and making them in a way that supports and strengthens the community, the philosophy, the standards, and the product is always the RIGHT choice. Even if you do not like it.
And does it really matter if a feature takes and extra cycle to implement to make sure everyone is happy with it and the way it is implemented? It never really has before, so why now? I am willing to wait for it to be done RIGHT, instead of just fast!
The whole incident emphasizes the extent to which these ostensibly technical debates are often settled by personality and emotion, rather than by technical excellence. //
It looks likely that Overstreet has upset too many important, influential people, and hurt too many feelings — and as a result, Linux is not going to get a new next-gen copy-on-write filesystem. It's a significant technological loss, and it's all down to people not getting along, rather than the shared desire to create a better OS. ®
To check the CPU temperature on FreeBSD, you can use the command sysctl -a | grep temperature after loading the appropriate driver for your CPU type with kldload coretemp for Intel or kldload amdtemp for AMD processors. Make sure to add the driver to /boot/loader.conf for automatic loading at boot time.
Sunrise, sunset, moon phase


We have setup MikroTik in different environments, its time for us to build IPsec tunnel between two sites where we have MikroTik routers.
Records revealed in the suit from police sergeant Charlotte Djossou showed that department leadership directed subordinates to file theft and violent crimes as lower-level offenses
These parasites are usually found in the skin, but they can invade anything.
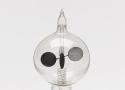
Most people would recognize the device in the image above, although they probably wouldn't know it by its formal name: the Crookes radiometer. As its name implies, placing the radiometer in light produces a measurable change: the blades start spinning. //
It's quite common—and quite wrong—to see explanations of the Crookes radiometer that involve radiation pressure. Supposedly, the dark sides of the blades absorb more photons, each of which carries a tiny bit of momentum, giving the dark side of the blades a consistent push. The problem with this explanation is that photons are bouncing off the silvery side, which imparts even more momentum. If the device were spinning due to radiation pressure, it would be turning in the opposite direction than it actually does.
An excess of the absorbed photons on the dark side is key to understanding how it works, though. Photophoresis operates through the temperature difference that develops between the warm, light-absorbing dark side of the blade and the cooler silvered side. //
But a Crookes radiometer is in a sealed glass container with a far lower air pressure. This allows the gas molecules to speed off much farther from the dark surface of the blade before they run into anything, creating an area of somewhat lower pressure at its surface. That causes gas near the surface of the shiny side to rush around and fill this lower-pressure area, imparting the force that starts the blades turning.
Just who are the greatest aerospace engineers of all time? The ability to fly has long been an ambitious quest for mankind. Many centuries have been spent trying to master the art, as such there have been many aerospace engineers with a profound and lasting impact. Here at MNB Precision we have compiled a list of both the greatest engineers and the greatest aerospace engineers. Ranging from the most famous and prominent to some lesser known yet still crucial figures, these are some of the best professionals in the field.

Have you ever wanted to learn to edit Wikipedia, but got overwhelmed? This video will help you get started contributing to one of the best projects on the web.
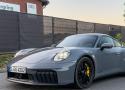
having spent several days behind the wheel, I can report it might just be one of the best-driving, too. //
This is not just one of Porsche's existing flat-six engines with an electric motor bolted on; it's an all-new 3.6 L engine designed to comply with new European legislation that no longer lets automakers rich out a fuel mixture under high load to improve engine cooling. Instead, the engine has to maintain the same 14.7:1 stoichiometric air-to-fuel ratio (also known as lambda = 1) across the entire operating range, thus allowing the car's catalytic converters to work most efficiently. //
for the first time in several decades, there's now only a single turbocharger. Normally, a larger-capacity engine and a single big turbo should be a recipe for plenty of lag, versus a smaller displacement and a turbocharger for each cylinder bank, as the former has larger components with more mass that needs to be moved.
That's where one of the two electric motors comes in. This one is found between the compressor and the turbine wheel, and it's only capable of 15 hp (11 kW), but it uses that to spin the turbine up to 120,000 rpm, hitting peak boost in 0.8 seconds. For comparison, the twin turbos you find in the current 3.0 L 911s take three times as long. Since the turbine is electrically controlled and the electric motor can regulate boost pressure, there's no need for a wastegate.
The electrically powered turbocharger is essentially the same as the MGU-H used in Formula 1, as it can drive the turbine and also regenerate energy to the car's traction battery. //
A command-line utility for retrieving files using HTTP, HTTPS and FTP protocols.
This guy literally dropped a 3-hour masterclass on building an web AI business from scratch
Gabor Mate, Scattered Minds

ne way to do it:
Dump trigger definitions into a file
# mysqldump -uroot -p --triggers --add-drop-trigger --no-create-info \
      --no-data --no-create-db --skip-opt test > /tmp/triggers.sql
Open triggers.sql file in your favorite editor and use Find and Replace feature to change DEFINERs. Save updated file.
Recreate triggers from the file
# mysql -u USER -p DATABASENAME < /tmp/triggers.sql

Zach Kessel @zach_kessel
·
NEW from @alanagoodman: Deposition and phone call transcripts, internal Metropolitan Police Department emails, and court documents show a systematic policy of misclassifying crimes to artificially lower DC crime statistics.
https://freebeacon.com/crime/a-dc-police-sergeant-exposed-her-superiors-for-misclassifying-crimes-to-make-stats-look-low-the-city-just-quietly-settled-her-lawsuit/
7:53 AM · Aug 14, 2025
Anna Giaritelli @Anna_Giaritelli
·
Thank you @LarryOConnor and @bethanyshondark for having me on @WMALDC to talk about how DC crime has impacted me personally.
‘A man went to prison for assaulting me. DC Police crime stats show he was never arrested’
washingtonexaminer.com
A man went to prison for assaulting me. DC crime stats don't show it
7:51 AM · Aug 14, 2025
Let's just say that there are some pockets being filled, and they are not yours or mine. Kerry called climate change a gold mine for investors, and he sure has been right.
The steps below aim to illustrate how to setup a site to site VPN between two Mikrotik devices using WireGuard. Pre-existing local networks and firewalls exist on both R1 and R2. Between R1 and R2 the WireGuard tunnel will use 172.17.0.0/30. R2 has 172.17.0.1 assigned to its WireGuard interface, while R1 has 172.17.0.2 assigned to its WireGuard interface. The network used, or the order in which IP addresses are assigned is not important, however it is considered best practice to use a point to point subnet between peers.