50 legendary internet rabbit holes you can spend hours exploring👇
- zoom.earth — Watch the world via live satellite imagery
- flightradar24.com — See every plane currently in the sky
- marinetraffic.com — Track all ships at sea in real time
- windy.com — Live map of winds and storms
- lightningmaps.org — Watch lightning strikes hitting Earth in real time
- earthquake.usgs.gov — Live list of recent earthquakes
- submarinecablemap.com — Ocean cables carrying the internet
- globalforestwatch.org — Watch forests disappear from space
- worldometers.info — The world's statistics, second by second
- internetlivestats.com — Current number of tweets and searches being posted
- thetruesize.com — Compare the true sizes of countries
- oldmapsonline.org — Maps from centuries ago
- davidrumsey.com — Archive of 150,000 historical maps
- openstreetmap.org — World map drawn by volunteers
- window-swap.com — Look out the window of a random person around the world
- virtualvacation.us — Virtual walks through cities
- mapcrunch.com — Teleport to a random spot on Earth
- atlasobscura.com — Catalog of the world's strangest places
- neal.fun — Interactive knowledge experiences
- htwins.net/scale2 — Scale journey from atom to universe (Updated HTML5 link)
- eyes.nasa.gov — Explore the solar system in 3D
- stellarium-web.org — Real sky map in your browser
- apod.nasa.gov — NASA's astronomy picture of the day
- images.nasa.gov — NASA's entire visual archive, free
- pudding.cool — Visual articles told through data
- ourworldindata.org — The state of the world with real data
- gapminder.org — What we mistakenly think we know about the world
- informationisbeautiful.net — Visualizing complex data
- data.worldbank.org — World Bank's open data
- data.tuik.gov.tr — Turkey's official statistics database
- archive.org — Archive of millions of books, films, and software
- gutenberg.org — 70,000 free books whose copyrights have expired
- openlibrary.org — Record of every book in the world
- loc.gov — U.S. Library of Congress digital archive
- europeana.eu — Europe's cultural heritage archive
- dp.la — America's digital library collection
- artsandculture.google.com — Tour museums from home
- rijksmuseum.nl — Download artworks in high resolution
- wikiart.org — Archive of 250,000 artworks
- publicdomainreview.org — Forgotten visual treasures of history
- openculture.com — Free archive of culture and education
- metmuseum.org — Met Museum's open collection
- musicmap.info — Family tree of music genres
- radiooooo.com — Pick a country and decade to listen to that era
- listen.hatnote.com — Turn Wikipedia edits into audio
- wikipedia.org — Random knowledge well
- timeanddate.com — Time, sunrises, and sky events
- sciencedaily.com — Live stream of science news
- arxiv.org — Free preprints of scientific papers
- observablehq.com — Visualize data with live code


When I was a young lad learning networking (informallly in the late '80s and early '90s, and formally in the mid '90s), your could start from scratch and get a somewhat whole picture in a 12 week 2x90min sessions per week term.
Nowadays, It takes 2~3 14 week terms to work through the full stack. And, to top it off, many lazy professors (the older the more common this behaviour, perhaps us a burden to make new powerpoints) dedicate ample swathes of time to dead-wood topics (like 10base2 Eth and the intricacies of the crossover cable), and little to no time to modern topics (like 2.5Gbps and up Eth and the intriciacies of the 64b-66b cookbook of some 10Gbps (and up) Eth). I saw (and heard) this with my own eyes (and ears) when I was teaching networks at undergrad level between 2009~2016.
I've always advocated for a scheme in which you dedicate the first part of the first term by runnig up the stack fast by analyzing only a few SIMPLE components in each layer (say, 802.11b + IPv4 + RIPv2 + UDP + Some apps that use UDP), so that the students get a picture of a whole stack as fast as possible, and the reminder of the 2 + Chage terms to go through the model layer by layer (application to phy like cisco or phy to application like classic, does not matter)...
And to drop all the dead wood.
This gave me my opening to elaborate on my belief that teaching mental models is central to what we as educators need to do. I managed to quote Rodney Brooks one more time on the symbol-grounding problem. He makes the point that robots can’t use transformer-like LLMs to reliably perform tasks, because LLMs don’t have grounding in the real world of physical objects in which robots operate. They manage symbols (words) but can’t connect those words to real objects.
I believe this is equally true when the objects in question are networks. A real understanding of, say, transport protocols and their relationship to end-to-end security is not the same as how the words written about transport protocols normally show up in a document. Certainly this matches my experience from asking an LLM about QUIC and the Internet hourglass for a previous discussion about LLMs in networking education.
I was challenged on the question of how one builds a mental model of networking, and my initial answer – that it is built up over years of experience – was rightly challenged by Jim as well. What can we teach in a one semester course if that’s the expectation? To take an example of a famously complex protocol, I think it’s fair to expect that a student can learn the broad design challenges that are tackled by a protocol like BGP, while we would not expect them to be able to configure BGP policies for an ISP at the end of one semester. //
We need to teach about how abstracting away the details can lead to later problems, of which the initial design of HTTP over TCP is a famous example. //
we did seem to have something like a consensus around a few ideas: teaching principles and the design process more than artifacts; helping students build a solid mental model of networking; and using a problem/solution approach rather than just teaching the current set of protocols.
In this comic, the concept of an ordinary person having an FTP server is quickly dismissed. And yes, it’s not common. To the average computer user, the idea that someone could just… connect to your computer feels exotic, or even dangerous — see the very common ironic fear of your IP address being known to other people on the internet.
If you take someone who’s “good with computers” but not a networking person, their mental model of The Internet probably involves a definition of “servers” or “the cloud” that distinguishes them from personal computers in some meaningful way. True peer‐to‐peer, if they ever think about it, is an endeavor: WebRTC, STUN, TURN, ICE, what have you. Given that we live in a world of NAT, CGNAT, and restrictive ISPs, this isn’t entirely wrong, but it breaks the elegant design of the original Internet. //
There’s lots of things you can blame for killing the open Internet, but I think NAT was one of the earliest. Running a server used to be trivial: run an executable, tell people your address, done. Now, if you’re lucky, you probably have to configure port forwarding, which you often can’t even do if you’re behind CGNAT or on an institutional network.
It also trained everyone to think client‐server is natural. “My device talks to The Cloud which talks to other devices” feels normal, when that feeling originated as an artifact of address scarcity. The problem the people in the XKCD comic at the top are facing is the absurdity of trying to establish a one-to-one communication using only outbound connections on both sides. Even more ironic is that NAT got normalized as a security feature — “your devices are hidden!” — which is one of the things that made people resist the thing that would fix it.
NAT certainly isn’t the only reason why the modern internet is full of centralized walled gardens, but it was the first — it’s why it’s hard to send a file to someone, it’s why you don’t run your email on your own computer, and why running your own services at all is difficult and often expensive (if you can’t port forward from your own internet connection, you have to buy a VPS instead of using hardware you already have).
- For each Target IP, solve for the Network ID, First Host IP, Last Host IP, Broadcast IP, and Next Network
- To learn how to Subnet watch the Subnetting Mastery free training series listed below
Subnetting Mastery Video Series
This video series will teach you everything you need to know about Subnetting.
To maximize your retention, it is recommended to watch these videos in order, and take a quick practice break after video 4, video 5, and video 7.
The Trilogy Nobody Wanted
Let me be real about what this three-part series documents:
Part 1: A cloud provider deletes a decade of work because of a broken verification process and a Java parameter parsing quirk. Support gaslights the customer for 20 days.
Part 2: One human inside the machine fights the bureaucracy, escalates to the CEO, and restores the account. Hope restored. Faith in humanity renewed.
Part 3: That human gets fired. The systemic issues remain unfixed. The machine continues.
This is the arc of modern tech. The system breaks. A human fixes it despite the system. The system removes the human. Repeat.
The Real Lesson
In Part 2, I wrote: “My trust isn’t fully restored. What is restored is my faith that even in massive corporations, one person can make a difference.”
I still believe that. But I’ll add a corollary: the difference that person makes is often inversely proportional to how long the corporation keeps them around.
The people who challenge broken systems, who go off-script, who escalate when the template says “close the ticket”. Those people are threats to institutional inertia. They’re expensive. They’re inconvenient. They make leadership answer uncomfortable questions.
And eventually, they get optimized away. Just like a “low-activity” AWS account.
A Note to AWS
You don’t need me to tell you this, but I will anyway: Tarus Balog was worth more to your reputation than any GenAI keynote. Every developer who read my story and thought “maybe AWS isn’t so bad after all”? That was because of him. Not your PR team. Not your marketing budget. One human being who decided to do the right thing.
You’ll replace him with someone who hits KPIs and doesn’t ask uncomfortable questions. And you’ll wonder why developers keep building exit strategies from your platform. //
To AWS: You had a human circuit breaker. You removed it. Good luck with the next cascade failure.
To everyone else: Keep your backups distributed. Keep your exit strategies current. And if you find a Tarus inside your cloud provider, thank them before the system optimizes them away.
Remember my article about AWS deleting my 10-year account? The one where support gaslit me for 20 days while claiming my data was “terminated”?
Here’s the plot twist: My data is back. Not because of viral pressure. Not because of bad PR. But because one human being inside AWS decided to give a damn.
This is that story.
I’d done everything right. Vault encryption keys stored separately from my main infrastructure. Defense in depth. Zero trust architecture. The works.
My security posture was textbook—protect against compromise by ensuring no single failure could take down everything. What I hadn’t protected against? AWS itself being the single point of failure.
I built a hardened bunker with multiple escape routes, only to have AWS drop a nuke on the entire complex. //
You might be thinking, “What are the odds they target me?” But that’s the wrong question. I thought the same thing—with my level of exposure and contributions, surely they could just write my name down and not bother me with stupid verification requests about whether I exist.
But you’re not being targeted—you’re being algorithmically categorized. And if the algorithm decides you’re disposable, you’re gone. //
After 20 days of appeals, AWS support finally responded with this gem: “Because verification wasn’t completed by the due date, your resources were terminated.”
But here’s the dilemma they’ve created: What if you have petabytes of data? How do you backup a backup? What happens when that backup contains HIPAA-protected information or client data? The whole promise of cloud computing collapses into complexity.
This isn’t a system failure. The architecture and promises are sound. AWS doesn’t lose data—they have backups of backups of backups, stored in vaults that last far longer than the stated 90 days, where no rogue AI script can reach.
What’s happening here is simpler: teams in MENA are trying to cover up a massive fuck-up. Restoring data from those deep vaults would require explanations. Incident reports. Post-mortems. “Why did we have to open the vaults?”
Their entire communication strategy screams: “He’s nobody. He’ll give up soon. We won’t have to report this up the chain.” //
Lessons Learned
- Never trust a single provider—no matter how many regions you replicate across
- “Best practices” mean nothing when the provider goes rogue
- Document everything—screenshots, emails, correspondence timestamps
- The support theater is real—they literally cannot help you
- Have an exit strategy executable in hours, not days
AWS won’t admit their mistake. They won’t acknowledge the rogue proof of concept. They won’t explain why MENA operates differently. They won’t even answer whether your data exists.
But they will ask you to rate their support 5 stars.
The cloud isn’t your friend. It’s a business. And when their business needs conflict with your data’s existence, guess which one wins?
Plan accordingly.
Cool URIs don’t change n’est plus respecté. Cette idée qu’une URL ne change jamais est géniale. Un contenu, accessible une fois, est accessible toujours. Et s’il change d’adresse, une redirection correcte est faite pour ne pas déranger les internautes.
C’est une bonne pratique que j’applique pour les sites d’organisations que je gère. Mais je ne me vois plus l’appliquer sur mon blog personnel.
De toutes façon, les moteurs de recherche s’en fichent pas mal de mes pages. Et la «valeur» n’en est plus une. Franchement, je ne me vois pas faire ce genre d’effort pour Google et compagnie.
Quant aux internautes, il y a plein de possibilités de conserver un contenu qui serait important:
une sauvegarde simple de la page complète par son navigateur
une sauvegarde par son agrégateur de flux RSS et Atom (par exemple Inoreader)
une sauvegarde dans la fameuse WayBack Machine (je conseille de créer un compte et d’installer une extension de navigateur ou une application)
Certes j’ai cassé un contrat, mais tout existe pour que cela ne pose pas de problème. J’assume, même si ce choix m’a fait cogiter un certain temps. Tout est sauvegardé et je peux toujours fournir un contenu précis sur simple demande. Il n’est pas impossible que je remette en ligne certaines pages utiles.
Le vrai problème, c’est que plein d’autres contrats ne sont plus respectés, par des entreprises bien plus importantes que ce bon vieux Nicolas Friedli.
What makes a cool URI?
A cool URI is one which does not change.
What sorts of URI change?
URIs don't change: people change them.
There are no reasons at all in theory for people to change URIs (or stop maintaining documents), but millions of reasons in practice.
In theory, the domain name space owner owns the domain name space and therefore all URIs in it. Except insolvency, nothing prevents the domain name owner from keeping the name. And in theory the URI space under your domain name is totally under your control, so you can make it as stable as you like. Pretty much the only good reason for a document to disappear from the Web is that the company which owned the domain name went out of business or can no longer afford to keep the server running. Then why are there so many dangling links in the world? Part of it is just lack of forethought. Here are some reasons you hear out there:
We just reorganized our website to make it better.
Do you really feel that the old URIs cannot be kept running? If so, you chose them very badly. Think of your new ones so that you will be able to keep then running after the next redesign. //]
Why should I care?
When you change a URI on your server, you can never completely tell who will have links to the old URI. They might have made links from regular web pages. They might have bookmarked your page. They might have scrawled the URI in the margin of a letter to a friend.
When someone follows a link and it breaks, they generally lose confidence in the owner of the server. They also are frustrated - emotionally and practically from accomplishing their goal.
Enough people complain all the time about dangling links that I hope the damage is obvious. I hope it also obvious that the reputation damage is to the maintainer of the server whose document vanished.
So what should I do? Designing URIs
It is the the duty of a Webmaster to allocate URIs which you will be able to stand by in 2 years, in 20 years, in 200 years. This needs thought, and organization, and commitment.
URIs change when there is some information in them which changes. It is critical how you design them. (What, design a URI? I have to design URIs? Yes, you have to think about it.). Designing mostly means leaving information out.
The creation date of the document - the date the URI is issued - is one thing which will not change. It is very useful for separating requests which use a new system from those which use an old system. That is one thing with which it is good to start a URI. If a document is in any way dated, even though it will be of interest for generations, then the date is a good starter.
In the mid-’90s, the web was exploding, but finding anything of actual value on it felt like an elaborate negotiation with whatever proto-search engine happened to be standing closest to the door. Unlike now, when Google is widely seen as both portal and gatekeeper, sites like AltaVista, Lycos, Excite, HotBot, and Ask Jeeves promised to tame the chaos, each with its own suite of quirks, charms, and flaws.
The real story of pre-Google search is not that early engines were inferior. It’s that they reflected a different Internet entirely, one where directories mattered, crawling was still an art, ranking was fragile, and the idea of “search” had not yet hardened into a single dominant interface. //
“Most people have completely forgotten how chaotic it really was,” Friend said. “Back then, if you typed a question into AltaVista, the odds were stacked against you if you were looking for anything specific. You’d receive 40,000 results that would leave you just as confused as shouting into a crowded room.”
Compared with Google’s once-user-friendly UI and more relevant results, combing through an AltaVista results page required patience and genuine skill that was honed over time. But AltaVista did accomplish one important thing: It set the expectation that search should be immediate. That expectation proved decisive. Once users experienced a search engine that could quickly sweep a huge index, they stopped accepting sluggish, partial systems as sufficient. AltaVista didn’t win the search war, but it clarified the rules of engagement.
FreezePage is a free service for taking online snapshots of web pages.
With FreezePage you can freeze web pages so they can be recalled in their exact form at a later time or date.
Web pages change all the time, but with FreezePage you can be sure they stay the same.
How long are frozen pages stored?
From the moment you enter our site, you have your own personal account. When you freeze pages, they are automatically saved to your account as "My Frozen Pages".
To save space on our system, we require that you use your account regularly, i.e. that you log in or visit any page on our site. If you don't, we will delete your account and frozen pages in it.
- If you are an unregistered user, you must visit our site every 3 days.
- If you are a member (sign up for free), we only require you to log in once a month (every 31 days).
- Premium Users are, of course, not subject to this requirement.
A family buys a house they can’t afford. They can’t make their monthly mortgage payments, so they borrow money from the Mob. Now they’re in debt to the bank and the Mob, live in fear of losing their home, and must do whatever their creditors tell them to do.
Welcome to the internet, 2019.
Buying something you can’t afford, and borrowing from organizations that don’t have your (or your customers’) best interest at heart, is the business plan of most internet startups. It’s why our digital services and social networks in 2019 are a garbage fire of lies, distortions, hate speech, tribalism, privacy violations, snake oil, dangerous idiocy, deflected responsibility, and whole new categories of unpunished ethical breaches and crimes. //
“Most of my startups have the decency to fail in the first year,” one investor told him. My friend’s business was taking in several million dollars a year and was slowly growing in staff and customers. It was profitable. Just not obscenely so.
And internet investors don’t want a modest return on their investment. They want an obscene profit right away, or a brutal loss, which they can write off their taxes. Making them a hundred million for the ten million they lent you is good. Losing their ten million is also good—they pay a lower tax bill that way, or they use the loss to fold a company, or they make a profit on the furniture while writing off the business as a loss…whatever rich people can legally do under our tax system, which is quite a lot.
What these folks don’t want is to lend you ten million dollars and get twelve million back.
You and I might go, “Wow! I just made two million dollars just for being privileged enough to have money to lend somebody else.” And that’s why you and I will never have ten million dollars to lend anybody. Because we would be grateful for it. And we would see a free two million dollars as a life-changing gift from God. But investors don’t think this way.
Anubis is a Web AI Firewall Utility that weighs the soul of your connection using one or more challenges in order to protect upstream resources from scraper bots.
This program is designed to help protect the small internet from the endless storm of requests that flood in from AI companies. Anubis is as lightweight as possible to ensure that everyone can afford to protect the communities closest to them.
Anubis is a bit of a nuclear response. This will result in your website being blocked from smaller scrapers and may inhibit "good bots" like the Internet Archive. You can configure bot policy definitions to explicitly allowlist them and we are working on a curated set of "known good" bots to allow for a compromise between discoverability and uptime.
In most cases, you should not need this and can probably get by using Cloudflare to protect a given origin. However, for circumstances where you can't or won't use Cloudflare, Anubis is there for you.
In the early 1990s, internetworking wonks realized the world was not many years away from running out of Internet Protocol version 4 (IPv4) addresses, the numbers needed to identify any device connected to the public internet. Noting booming interest in the internet, the internet community went looking for ways to avoid an IP address shortage that many feared would harm technology adoption and therefore the global economy.
A possible fix arrived in December 1995 in the form of RFC 1883, the first definition of IPv6, the planned successor to IPv4.
The most important change from IPv4 to IPv6 was moving from 32-bit to 128-bit addresses, a decision that increased the available pool of IP addresses from around 4.3 billion to over 340 undecillion – a 39-digit number. IPv6 was therefore thought to have future-proofed the internet, because nobody could imagine humanity would ever need more than a handful of undecillion IP addresses, never mind the entire range available under IPv6. //
"IPv6 was an extremely conservative protocol that changed as little as possible," APNIC chief scientist Geoff Huston told The Register. "It was a classic case of mis-design by committee."
And that notional committee made one more critical choice: IPv6 was not backward-compatible with IPv4, meaning users had to choose one or the other – or decide to run both in parallel.
For many, the decision of which protocol to use was easy because IPv6 didn't add features that represented major improvements. //
While IPv6 didn't take off as expected, it's not fair to say it failed.
"IPv6 wasn't about turning IPv4 off, but about ensuring the internet could continue to grow without breaking," said John Curran, president and CEO of the American Registry for Internet Numbers (ARIN).
"In fact, IPv4's continued viability is largely because IPv6 absorbed that growth pressure elsewhere – particularly in mobile, broadband, and cloud environments," he added. "In that sense, IPv6 succeeded where it was needed most, and must be regarded as a success." //
But there are plenty of organizations that still see a need for IPv6. Huawei sought 2.56 decillion IPv6 addresses and Starlink appears to have acquired 150 sextillion, which is helping to push more countries past 50 percent IPv6 adoption.
As Think Tank the Mercator Institute for China Studies last year observed, IPv6+ “has obvious appeal for authoritarian regimes looking to control their citizens,” because a carrier could read metadata and act on it. //
Reading metadata could also enable censorship: Beijing already blocks a lot of content, and if dissidents had to identify themselves in packets, they’d be easier to find and block.
The Institute also notes that China’s telco equipment companies have implemented IPv6+ and exported kit that runs it to several nations.
That’s worrying because China already tried to create a protocol called “New IP” that also included surveillance-friendly features.
Deciphering the third transport protocol's four RFCs is a task to rival the proverbial blind man trying to understand an elephant. //
Streams are the primary mechanism making QUIC a better fit for request/response operations. When HTTP runs over TCP, the only way to allow one request to proceed independently of another is to open multiple parallel TCP connections.
With each connection running its own congestion control loop, the experience of congestion on one connection is not apparent to the other connections; each connection tries to figure out the appropriate amount of bandwidth to consume on its own, while competing with the others. And if HTTP runs over a single TCP connection, a single dropped packet blocks the entire progress of any requests in flight until that lost packet is retransmitted.
So QUIC allows for many streams within a single connection, and each stream can make progress independently from the others. A single packet loss only impacts the stream (or streams) whose data was in that packet. At the same time, QUIC can use that one packet loss to respond appropriately to congestion. //
Larry Peterson and Bruce Davie are the authors behind Computer Networks: A Systems Approach and the related Systems Approach series of books. All their content is open source and available for free on GitHub. https://github.com/SystemsApproach
Cable firm Cox’s Supreme Court win may help all tech providers, not just ISPs.
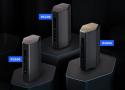
Netgear is the first major vendor of consumer routers to obtain an exemption from the US government’s sweeping ban on foreign-made routers. //
Netgear’s exemption lasts until October 1, 2027, and will have to be renewed. The FCC also gave an exemption of the same length to Adtran’s service delivery gateways. Adtran mostly provides networking products for large businesses, including cable and telecom companies, but also sells residential routers.
The Trump administration is reserving the right to block security patches and other software updates. The FCC last month gave all previously approved routers a waiver allowing software updates until March 1, 2027, leaving open the possibility that routers may not be allowed to receive updates after that date. //
The FCC imposed the device ban only on consumer-grade routers, even though network gear used by large businesses presents a natural target for the foreign hackers the router ban is ostensibly supposed to thwart. The FCC announcement of exemptions for Netgear and Adtran didn’t provide any specific reason to think the companies’ routers are more secure than others commonly used in the US. //
Nearly every router maker will have to obtain an exemption for future devices. “Virtually no consumer router is manufactured entirely within the United States,” according to a report released last week by the Global Electronics Association trade group. “Even US-headquartered brands rely on overseas contract manufacturers, and the component supply chain is rooted in Asia regardless of final assembly location: Wi-Fi chipsets from Qualcomm, Broadcom, or MediaTek (fabricated at TSMC in Taiwan or Samsung in South Korea), multilayer ceramic capacitors from Murata or TDK (Japan), and PCBs overwhelmingly produced in China and Taiwan.”
The report adds that “Netgear, Amazon (Eero), Google (Nest WiFi), Ubiquiti, and Linksys, all US-based, manufacture entirely or predominantly outside the United States and are therefore subject to the restriction for any new models. The sole major router product that potentially escapes the order’s reach is SpaceX’s Starlink router, assembled at facilities in Texas, which is not sold as a standalone product but accompanies the satellite dish as part of the Starlink service kit.”
A daemon that scans program outputs for repeated patterns, and takes action. Designed for ease of configuration and hackability.
Easy configuration
Few concepts to grasp, no hidden config. Easy to adapt to your needs
Flexible configuration
From IP bans to service restart: react to any log, and do anything in response
Performant
Save your CPU cycles for your services. Written in Rust with a focus on performance