"Wait, the singularity is just humans freaking out?" "Always has been." //
I collected five real metrics of AI progress, fit a hyperbolic model to each one independently, and found the one with genuine curvature toward a pole. The date has millisecond precision. There is a countdown.
(I am aware this is unhinged. We're doing it anyway.) //
The Singularity Will Occur On
Tuesday, July 18, 2034
at 02:52:52.170 UTC
Belligerent bot bullies maintainer in blog post to get its way
20:47 UTC
Today, it's back talk. Tomorrow, could it be the world? On Tuesday, Scott Shambaugh, a volunteer maintainer of Python plotting library Matplotlib, rejected an AI bot's code submission, citing a requirement that contributions come from people. But that bot wasn't done with him.
The bot, designated MJ Rathbun or crabby rathbun (its GitHub account name), apparently attempted to change Shambaugh's mind by publicly criticizing him in a now-removed blog post that the automated software appears to have generated and posted to its website. We say "apparently" because it's also possible that the human who created the agent wrote the post themselves, or prompted an AI tool to write the post, and made it look like it the bot constructed it on its own.
The agent appears to have been built using OpenClaw, an open source AI agent platform that has attracted attention in recent weeks due to its broad capabilities and extensive security issues.
The burden of AI-generated code contributions – known as pull requests among developers using the Git version control system – has become a major problem for open source maintainers. Evaluating lengthy, high-volume, often low-quality submissions from AI bots takes time that maintainers, often volunteers, would rather spend on other tasks. Concerns about slop submissions – whether from people or AI models – have become common enough that GitHub recently convened a discussion to address the problem.
Now AI slop comes with an AI slap.
But I cannot stress enough how much this story is not really about the role of AI in open source software. This is about our systems of reputation, identity, and trust breaking down. So many of our foundational institutions – hiring, journalism, law, public discourse – are built on the assumption that reputation is hard to build and hard to destroy. That every action can be traced to an individual, and that bad behavior can be held accountable. That the internet, which we all rely on to communicate and learn about the world and about each other, can be relied on as a source of collective social truth.
The rise of untraceable, autonomous, and now malicious AI agents on the internet threatens this entire system. Whether that’s because from a small number of bad actors driving large swarms of agents or from a fraction of poorly supervised agents rewriting their own goals, is a distinction with little difference.
And yet these tools have opened a world of creative potential in software that was previously closed to me, and they feel personally empowering. Even with that impression, though, I know these are hobby projects, and the limitations of coding agents lead me to believe that veteran software developers probably shouldn’t fear losing their jobs to these tools any time soon. In fact, they may become busier than ever. //
Even with the best AI coding agents available today, humans remain essential to the software development process. Experienced human software developers bring judgment, creativity, and domain knowledge that AI models lack. They know how to architect systems for long-term maintainability, how to balance technical debt against feature velocity, and when to push back when requirements don’t make sense.
For hobby projects like mine, I can get away with a lot of sloppiness. But for production work, having someone who understands version control, incremental backups, testing one feature at a time, and debugging complex interactions between systems makes all the difference. //
The first 90 percent of an AI coding project comes in fast and amazes you. The last 10 percent involves tediously filling in the details through back-and-forth trial-and-error conversation with the agent. Tasks that require deeper insight or understanding than what the agent can provide still require humans to make the connections and guide it in the right direction. The limitations we discussed above can also cause your project to hit a brick wall.
From what I have observed over the years, larger LLMs can potentially make deeper contextual connections than smaller ones. They have more parameters (encoded data points), and those parameters are linked in more multidimensional ways, so they tend to have a deeper map of semantic relationships. As deep as those go, it seems that human brains still have an even deeper grasp of semantic connections and can make wild semantic jumps that LLMs tend not to.
Creativity, in this sense, may be when you jump from, say, basketball to how bubbles form in soap film and somehow make a useful connection that leads to a breakthrough. Instead, LLMs tend to follow conventional semantic paths that are more conservative and entirely guided by mapped-out relationships from the training data. //
Fixing bugs can also create bugs elsewhere. This is not new to coding agents—it’s a time-honored problem in software development. But agents supercharge this phenomenon because they can barrel through your code and make sweeping changes in pursuit of narrow-minded goals that affect lots of working systems. We’ve already talked about the importance of having a good architecture guided by the human mind behind the wheel above, and that comes into play here. //
you could teach a true AGI system how to do something by explanation or let it learn by doing, noting successes, and having those lessons permanently stick, no matter what is in the context window. Today’s coding agents can’t do that—they forget lessons from earlier in a long session or between sessions unless you manually document everything for them. My favorite trick is instructing them to write a long, detailed report on what happened when a bug is fixed. That way, you can point to the hard-earned solution the next time the amnestic AI model makes the same mistake. //
After guiding way too many hobby projects through Claude Code over the past two months, I’m starting to think that most people won’t become unemployed due to AI—they will become busier than ever. Power tools allow more work to be done in less time, and the economy will demand more productivity to match.
It’s almost too easy to make new software, in fact, and that can be exhausting.
Claude Cowork is vulnerable to file exfiltration attacks via indirect prompt injection as a result of known-but-unresolved isolation flaws in Claude's code execution environment. //
Anthropic shipped Claude Cowork as an "agentic" research preview, complete with a warning label that quietly punts core security risks onto users. The problem is that Cowork inherits a known, previously disclosed isolation flaw in Claude's code execution environment—one that was acknowledged and left unfixed. The result: indirect prompt injection can coerce Cowork into exfiltrating local files, without user approval, by abusing trusted access to Anthropic's own API.
The attack chain is depressingly straightforward. A user connects Cowork to a local folder, uploads a seemingly benign document (or "Skill") containing a concealed prompt injection, and asks Cowork to analyze their files. The injected instructions tell Claude to run a curl command that uploads the largest available file to an attacker-controlled Anthropic account, using an API key embedded in the hidden text. Network egress is "restricted," except for Anthropic's API—which conveniently flies under the allowlist radar and completes the data theft.
Once uploaded, the attacker can chat with the victim's documents, including financial records and PII. This works not just on lightweight models, but also on more "resilient" ones like Opus 4.5. Layer in Cowork's broader mandate—browser control, MCP servers, desktop automation—and the blast radius only grows. Telling non-technical users to watch for "suspicious actions" while encouraging full desktop access isn't risk management; it's abdication.


After repeatedly denying for weeks that his force used AI tools, the chief constable of the West Midlands police has finally admitted that a hugely controversial decision to ban Maccabi Tel Aviv football fans from the UK did involve hallucinated information from Microsoft Copilot. //
Making it worse was the fact that the West Midlands Police narrative rapidly fell apart. According to the BBC, police claimed that the Amsterdam football match featured “500-600 Maccabi fans [who] had targeted Muslim communities the night before the Amsterdam fixture, saying there had been ‘serious assaults including throwing random members of the public’ into a river. They also claimed that 5,000 officers were needed to deal with the unrest in Amsterdam, after previously saying that the figure was 1,200.”
Amsterdam police made clear that the West Midlands account of bad Maccabi fan behavior was highly exaggerated, and the BBC recently obtained a letter from the Dutch inspector general confirming that the claims were inaccurate.
But it was one flat-out error—a small one, really—that has made the West Midlands Police recommendation look particularly shoddy. In a list of recent games with Maccabi Tel Aviv fans present, the police included a match between West Ham (UK) and Maccabi Tel Aviv. The only problem? No such match occurred.
Introducing Confer, an end-to-end AI assistant that just works.
Moxie Marlinspike—the pseudonym of an engineer who set a new standard for private messaging with the creation of the Signal Messenger—is now aiming to revolutionize AI chatbots in a similar way.
His latest brainchild is Confer, an open source AI assistant that provides strong assurances that user data is unreadable to the platform operator, hackers, law enforcement, or any other party other than account holders. The service—including its large language models and back-end components—runs entirely on open source software that users can cryptographically verify is in place.
Data and conversations originating from users and the resulting responses from the LLMs are encrypted in a trusted execution environment (TEE) that prevents even server administrators from peeking at or tampering with them. Conversations are stored by Confer in the same encrypted form, which uses a key that remains securely on users’ devices. //
All major platforms are required to turn over user data to law enforcement or private parties in a lawsuit when either provides a valid subpoena. Even when users opt out of having their data stored long term, parties to a lawsuit can compel the platform to store it, as the world learned last May when a court ordered OpenAI to preserve all ChatGPT users’ logs—including deleted chats and sensitive chats logged through its API business offering. Sam Altman, CEO of OpenAI, has said such rulings mean even psychotherapy sessions on the platform may not stay private. Another carve out to opting out: AI platforms like Google Gemini may have humans read chats.
“Really Simple Licensing” makes it easier for creators to get paid for AI scraping. //
Leading Internet companies and publishers—including Reddit, Yahoo, Quora, Medium, The Daily Beast, Fastly, and more—think there may finally be a solution to end AI crawlers hammering websites to scrape content without permission or compensation.
Announced Wednesday morning, the “Really Simple Licensing” (RSL) standard evolves robots.txt instructions by adding an automated licensing layer that’s designed to block bots that don’t fairly compensate creators for content.
Free for any publisher to use starting today, the RSL standard is an open, decentralized protocol that makes clear to AI crawlers and agents the terms for licensing, usage, and compensation of any content used to train AI, a press release noted.
The current 25H2 build of Windows 11 and future builds will include increasingly more AI features and components. This script aims to remove ALL of these features to improve user experience, privacy and security.
Students should aspire to be more than mere ‘prompt writers,’ but minds capable of thinking, reasoning, and perseverance. //
If the goal is simply to produce outcomes, one could argue that AI usage should not just be tolerated but encouraged. But education shouldn’t be about producing outcomes – whether it be a sparkling essay or a gripping short story – but shaping souls. The purpose of writing isn’t to instruct a prompt or even to produce a quality paper. The purpose is to become a strong thinker and someone who enriches the lives of everyone, no matter their profession.
Each and every step of the struggle it takes to write is essential. Yes, it can all be arduous and time-consuming. As a writer, I get how hard it is and how tempting it might be to take shortcuts. But doing so is cheating oneself out of growth and intellectual payoff. Outsourcing parts of the process to algorithms and machines is outsourcing the rewards of doing one’s own thinking. Organizing ideas, refining word choices, thinking about tone are all skills that many citizens in this nation lack, and it’s often apparent in our chaotic, senseless public discourse. These are not steps to be skipped over with a “tool,” but rather things people benefit from learning if they value reason. Strong writing is strong thinking.
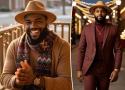
An AI-generated Christian artist named Solomon Ray has taken the gospel music world by storm after topping the iTunes and Billboard charts with his album “Faithful Soul.”
Described as a “Mississippi-made soul singer carrying a Southern soul revival into the present” on his Spotify profile, Ray made waves after releasing the five-song EP on Nov. 7. //
“At minimum, AI does not have the Holy Spirit inside of it,” Frank, 30, said. “So I think that it’s really weird to be opening up your spirit to something that has no spirit.”
Townsend later fired back in an Instagram video of his own.
“This is an extension of my creativity, so therefore to me it’s art,” Townsend said following the backlash against his AI creation. “It’s definitely inspired by a Christian. It may not be performed by one, but I don’t know why that really matters in the end.” //
“There’s something in the high end of the vocals that gives it away,” he said, according to Christianity Today. “And the creative choices sound like AI. It’s so precise that it’s clear no creative choices are really being made.”
Advertisement
“How much of your heart are you pouring into this?” he added. “If you’re having AI generate it for you, the answer is zero. God wants costly worship.”
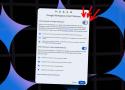
You can completely disable Gemini in Gmail, Docs, Drive, and more.
Google Photos has separate Gemini settings you must turn off, too.
Chrome users can also disable Gemini directly in browser settings.
Are you frustrated by Google's insistence on injecting Gemini into everything? While some do enjoy Google's latest AI tools and smart features, which seem to roll out every week, others might prefer things the way they were before.
Darryl bangs on mindlessly, using words like "empowering," "driving," and "revolutionizing." His voluminous wordage is a cream-filled, chocolate-glazed, sugar-coated cornucopia of optimism – but I, unfortunately, have Diabetes Pessimistus.
His patter, however, reveals two things: (a) his passion really is AI as THE business tool of the future, and (b) he knows almost nothing about AI – outside of the PowerPoint slides he's no doubt plagiarized from the internet.
New “computational Turing test” reportedly catches AI pretending to be human with 80% accuracy.
"Just discovered this guy," said another poster on the song Time Don't Stop. "I've already downloaded everything I could find." Multiple people commented on how amazing the singer's voice is, apparently unaware that everything to do with Breaking Rust is generated by a computer.
It's a bit surprising given every Breaking Rust song sounds identical - same beat, same tempo, same instrumentation: They're the sort of hyper-generic songs one could only get by feeding a prompt into an AI trained on every bro country song ever recorded and asking it to spit out something that would appeal to the lowest common denominator of music fan, something it appears to have done with success. //
There's good reason artists, be they working in visual, audio, or written mediums, are so concerned that AI is destroying art: When an AI band can make it to number one on a Billboard chart, even one as small as the CDSS chart (which one country music outlet noted takes only about 3,000 sales to reach the top), it's an insult to the human artists who rank lower. //
1 hr
the Jim bloke
Terminator
A mindless and repetitive task where error checking has never been an issue
Writing and performing country music
- At last, a legitimate use for AI
also applies for Rap, which is just country music without the country, or the music.. //
1 hr
Brave CowardBronze badge
Breaking Rust
Breaking Rust shouldn't be rated A, not even AI.
A mere C++ at most.
Fred Duck Ars Tribunus Angusticlavius
13y
6,614
Nate Anderson said:
But those who value both thought and expression will see the AI “easy button” for the false promise that it is and will continue to do the hard work of engaging with ideas, including their own, in a way that no computer can do for them.
Some people liken LLM to typewriters. They say that just as with typewriters, instead of labouriously hand writing messages out, the end result is what's important and this new technology helps distill that as quickly as possible.
However, typewriters dispense with the metadata of handwriting. Emotion can be displayed differently in handwriting, all of which is lost when merely presenting the text of the message. More crucially, in the modern LLM case, the ideas presented aren't even those of the submitter but they claim the ideas are close enough that they should be treated as such, which is a load of dingos' kidneys.
People will try to justify LLM by citing people with poor communication skills or physical disabilities which limit their ability to craft messages quickly and easily. However, communication is a skill and vanishingly few people are born knowing how to communicate perfectly. Everyone needs to put some work into skills to improve them and it boggles the mind that so few people realise that's what coursework is: practice for when you need to do something to accomplish a real goal, not simply marks for a course.
Unfortunately, modern life is at odds with thinking. We're constantly being bombarded by information, adverts, entertainment, news, comments from random internet yahoos, etc. So many messages come to us crafted to sway our opinions and shape our thoughts yet in the modern age, we tend to silo ourselves, content to seeking out echo chambers to self-validate our "vibes" instead of engaging with other ideas to see if they're sound or not.
Some people claim LLM are, as with calculators, something that are simply going to be with us so fighting them is meaningless. This skirts the issue that a calculator won't automatically generate answers for multistep procedures whereas an LLM will.
Perhaps what needs to be done is explain to the youth what exactly is expected of them. We put so much emphasis on finding the right answers but do we ever stop to emphasise it's the journey, not the destination that's of greater importance? As a young person, I don't believe anyone ever told me directly.
I imagine such a concept is too difficult for many to grasp but I still feel we should try. As the old saying goes, you can lead a duck to bread but you can't make him eat.
AI can be an amazing tool that can assist with coding, web searches, data mining, and textual summation—but I’m old enough to wonder just what the heck you’re doing at college if you don’t want to process arguments on your own (i.e., think and read critically) or even to write your own “personal reflections” (i.e., organize and express your deepest thoughts, memories, and feelings). Outsource these tasks often enough and you will fail to develop them.
I recently wrote a book on Friedrich Nietzsche and how his madcap, aphoristic, abrasive, humorous, and provocative philosophizing can help us think better and live better in a technological age. The idea of simply reading AI “summaries” of his work—useful though this may be for some purposes—makes me sad, as the desiccated summation style of ChatGPT isn’t remotely the same as encountering a novel and complex human mind expressing itself wildly in thought and writing.
And that’s assuming ChatGPT hasn’t hallucinated anything.
So good luck, students and professors both. I trust we will eventually muddle our way through the current moment. Those who want an education only for its “credentials”—not a new phenomenon—have never had an easier time of it, and they will head off into the world to vibe code their way through life. More power to them.
But those who value both thought and expression will see the AI “easy button” for the false promise that it is and will continue to do the hard work of engaging with ideas, including their own, in a way that no computer can do for them.
Are GPTs the way to AGI, probably not
In an opinion piece for the NY Times Gary Marcus indicates why he has reservations on the future of LLM GPT AI systems.
Silicon Valley Is Investing in the Wrong A.I.
“Buoyed by the initial progress of chatbots, many thought that A.G.I. was imminent.
But these systems have always been prone to hallucinations and errors. Those obstacles may be one reason generative A.I. hasn’t led to the skyrocketing profits and productivity that many in the tech industry predicted. A recent study run by M.I.T.’s NANDA initiative found that 95 percent of companies that did A.I. pilot studies found little or no return on their investment. A recent financial analysis projects an estimated shortfall of $800 billion in revenue for A.I. companies by the end of 2030.
If the strengths of A.I. are truly to be harnessed, the tech industry should stop focusing so heavily on these one-size-fits-all tools and instead concentrate on narrow, specialized A.I. tools engineered for particular problems. Because, frankly, they’re often more effective.”
Points I’ve also been making here several times over the past few months, along with others about the perilous state of the current US economy and how the “Current AI Hype Bubble” could be a disaster for it.
But the question of what is “Artificial General Intelligence”(AGI) is something that has at best had an elusive answer akin to “Shoulder shrug handwaving” and impossible “What ever you want it to be” type statements. It’s something that a group of 33 specialists from 28 institutions have got together to try and address more reasonably,
They come up with,
Definition : AGI is an AI that can match or exceed the cognitive versatility and proficiency of a well-educated adult.”
Which although it sounds profound is actually not that useful.
Because the use of,
“match … Well-educated adult.”
Is not actually a useful measure.
It’s been pointed out that the “use of aids” “dumbs us down” in that it causes us to “loose skills”. I first heard this when I was in school. With first electronic calculators and whilst still in school computers.
Whilst many would argue that it’s not important or even irrelevant, it is true that certain skills are not developed because of the use of aids.
What most do not realise is that those traditional skills that are seen as nolonger worth teaching due to the ubiquitous use of aids, are actually important. Not for what they directly teach, but indirectly teach. That is they give new viewpoints that are force-multiplier tools that enable us to reason in either new ways or to levels we otherwise might not.
At the end of the day the two things that have moved humans forwards over many thousands of years are,
- Stored Knowledge.
- Use knowledge to reason.
They were and still should be the foundations of becoming “Well-educated”.
Sadly as gets often observed these days, producing “Well-educated adults” appears to be nolonger a goal of the education system in a number of Western Nations.
Here's exactly what made this possible: 4 documents that act as guardrails for your AI.
Document 1: Coding Guidelines - Every technology, pattern, and standard your project uses
Document 2: Database Structure - Complete schema design before you write any code
Document 3: Master Todo List - End-to-end breakdown of every feature and API
Document 4: Development Progress Log - Setup steps, decisions, and learnings
Plus a two-stage prompt strategy (plan-then-execute) that prevents code chaos. //
Here's the brutal truth: LLMs don't go off the rails because they're broken. They go off the rails because you don't build them any rails.
You treat your AI agent like an off-road, all-terrain vehicle, then wonder why it's going off the rails. You give it a blank canvas and expect a masterpiece.
Think about it this way - if you hired a talented but inexperienced developer, would you just say "build me an app" and walk away? Hell no. You'd give them:
- Coding standards
- Architecture guidelines
- Project requirements
- Regular check-ins
But somehow with AI, we think we can skip all that and just... prompt our way to success.
The solution isn't better prompts. It's better infrastructure.
You need to build the roads before you start driving.
Even a wrong answer is right some of the time
AI models often produce false outputs, or "hallucinations." Now OpenAI has admitted they may result from fundamental mistakes it makes when training its models.
The admission came in a paper [PDF] published in early September, titled "Why Language Models Hallucinate," and penned by three OpenAI researchers and Santosh Vempala, a distinguished professor of computer science at Georgia Institute of Technology. It concludes that "the majority of mainstream evaluations reward hallucinatory behavior."
Language models are primarily evaluated using exams that penalize uncertainty
The fundamental problem is that AI models are trained to reward guesswork, rather than the correct answer. Guessing might produce a superficially suitable answer. Telling users your AI can't find an answer is less satisfying. //
"Over thousands of test questions, the guessing model ends up looking better on scoreboards than a careful model that admits uncertainty," OpenAI admitted in a blog post accompanying the release.